Family Tree

Family Tree

About Me

My photo
Kathmandu, Bagmati Zone, Nepal
I am Basan Shrestha from Kathmandu, Nepal. I use the term 'BASAN' as 'Balancing Actions for Sustainable Agriculture and Natural Resources'. I am a Design, Monitoring & Evaluation professional. I hold 1) MSc in Regional and Rural Development Planning, Asian Institute of Technology, Thailand, 2002; 2) MSc in Statistics, Tribhuvan University (TU), Kathmandu, Nepal, 1995; and 3) MA in Sociology, TU, 1997. I have more than 10 years of professional experience in socio-economic research, monitoring and documentation on agricultural and natural resource management. I had worked in Lumle Agricultural Research Centre, western Nepal from Nov. 1997 to Dec. 2000; CARE Nepal, mid-western Nepal from Mar. 2003 to June 2006 and WTLCP in far-western Nepal from June 2006 to Jan. 2011, Training Institute for Technical Instruction (TITI) from July to Sep 2011, UN Women Nepal from Sep to Dec 2011 and Mercy Corps Nepal from 24 Jan 2012 to 14 August 2016 and CAMRIS International in Nepal commencing 1 February 2017. I have published articles to my credit.

Wednesday, May 23, 2018

Probability Rule of Independence, Statistical Note 4

Two events are said to be independent if the occurrence of one event does not affect the occurrence of the another. In that case the probability of the second event given the first event is equal to the probability of the first event.

I take an example from my statistical note 3 to show whether the sex of participants is independent of the food habit of the participants. Table 1 presents data on the number of training participants by sex of participants and food habit.

Table 1: Food habit of training participants variable by sex


Here, I will take the case of the joint probability of the first cell, P(VÇW). The sex of participant is independent of the food habit if P(V/W) is equal to P(V) or if P(W/V) is equal to P(W). The P(V/W) is equal to 12 divided by 16, 0.75. The P(V) is equal to 18 divided by 40, 0.45. P(V/W) is not equal to P(V). In another case, P(W/V) is 12 divided by 18, 0.67. The PW) is equal to 16 divided by 40, 0.4. Here also, P(W/V) is not equal to P(W). These prove that the food habit of the participant is dependent on the sex of the participant.

Now, I will manipulate the cell values to show that the food habit is independent on the sex of the participants. The number of women and men participants by food habits were made equal. It shows that the number of vegetarians or non-vegetarians whether women or men are equal meaning food habit is not changed irrespective of sex of the participants. P(V/W) needs to be equal to P(V) or P(W/V) needs to be equal to P(W) to be the food habit independent of sex of the participant.

Table 2: Food habit of training participants invariable by sex
P(V/W) is 8 divided by 16, that is 0.50 and P(V) is 20 divided by 40, which is equal to 0.50. It shows that P(V/W) is equal to P(V). Likewise, P(W/V) is equal to 8 divided by 20, equal to 0.40 and P(W) is equal to 16 divided by 40, which is also equal to 0.40. This also shows that P(W/V) is equal to P(W). These shows that the probability using the multiplication rule of probability without replacement, denoted by  P(VÇW) equal to P(V/W) multiplied by P(W) is equal to the probability using the multiplication rule of probability with replacement, denoted by P(VÇW) equal to P(V) multiplied by P(W). Thus, food habit is independent of the sex of the participant.

Tuesday, May 22, 2018

Probability and Contingency Table: An Example, Statistical Note 3

I have taken an example from my statistical notes 1 and 2 to show the process of calculating the marginal, conditional and joint probabilities using the data presented in a contingency table, also known as the cross tabulation or crosstab. The cell values also are added to the crosstab as shown in table 1 below:

Table 1: Food habit of training participants by sex


This example has two discrete random variables or categorical variables each with two mutually exclusive categories of response. One categorical variable is the sex of training participants which has two categories of response: women (W) or men (M). Another categorical variable is the food habit which also has two mutually exclusive categories: vegetarian (V) and non-vegetarian (NV).

In the column total row, the simple or marginal probability of an independent event of women denoted by P(W) is 0.40, that is 40 percent of total training participants are women. This is calculated by dividing the column total or the marginal total of 16 women participants in the contingency table divided by the grand total of 40 participants. Likewise, the simple or marginal probability of an independent event of men denoted by P(M) is calculated at 0.60. Similar processes are followed in the row total column as well to calculate the simple or marginal probabilities of vegetarians denoted by P(V) equal to 0.45 and non-vegetarians denoted by P(NV) equal to 0.55 (table 2).

Table 2: Calculation of Marginal, Conditional and Joint Probabilities


The conditional probability of a vegetarian, a dependent event, given among the women represented by P(V/W) is 12 divided by 16, which is equal to 0.75, that is 75 percent women are vegetarians. Likewise, the conditional probabilities of P(NV/W), P(V/M) and P(NV/M) can be calculated following the same process. The conditional probabilities are also shown in table 2.

The joint probability that a randomly selected participant is a woman who is a vegetarian also, denoted by P(W intersection V) or P(WÇV) is the product of P(W) and P(V/W), the product of 0.4 and 0.75, equal to 0.30. This probability value is equal to the cross-sectional cell value between women column and vegetarian row divided by the grant total value in the contingency table, as shown in tables 2 and 3. The joint probabilities of P(WÇNV), P(MÇV) and P(MÇNV) can be calculated by using the same process.

Table 3: Cell values, Joint probabilities and cell values as percentage of grand total

Saturday, May 19, 2018

Conditional Probability Tree Diagram: Example, Statistical Note 2

A Tree Diagram is an important tool to visualize the events and their respective probabilities. I have taken an example from my statistical note 1 (Calculating the probability that a randomly selected person is a woman who is a vegetarian also) to show the process of drawing the probability tree diagram.

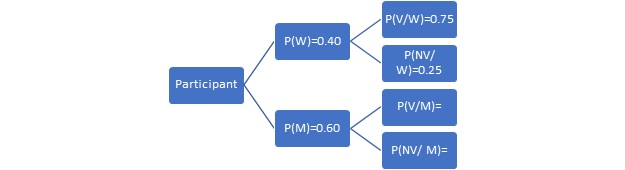
At the first step, there are two possible mutually exclusive or independent outcomes: women or men in the sample space of total training participants. The outcomes are independent because the selection of a woman does not depend on men. Let W be a simple event that a selected participant is a woman. The simple or marginal probability of the simple event W, denoted by P(W) is 0.40. It means that is 40 percent participants in the training are women. Another possible simple event is that the selected participant is a man, denoted by M and the simple or marginal probability of the event M denoted by P(M) is 0.60, that is 60 percent participants are men. These marginal probabilities at the first step are shown in the diagram, also referred to as the tree diagram 1.


Diagram 1: First step showing marginal probabilities
Once a woman is selected at the first step, there are two possible mutually exclusive dependent outcomes in the second step: vegetarian or non-vegetarian. Let V/W be an event that among the women participants, one is a vegetarian (V).  Now, the conditional probability of V/W denoted by P(V/W) is 0.75, that is 75 percent women participants are vegetarians. Likewise, let NV/W be an event that among the women participants, one is a non-vegetarian (NV).  The conditional probability of NV/W denoted by P(NV/W) is 0.25, that is 25 percent women participants are non-vegetarians. Similarly, conditional probabilities that a participant selected among women is a vegetarian or a non-vegetarian can be shown using a tree diagram 2.


Diagram 2: First and second steps showing marginal and conditional probabilities

Saturday, April 7, 2018

Calculating the probability that a randomly selected person is a woman who is a vegetarian also: An Example, Statistical Note 1

Of the total participants in a training, 40% are women and of the total women participants 75% are vegetarian. A participant is selected at random who is a woman, what is the probability that she is a vegetarian?

Calculating the probability of a "AND" compound event that a randomly selected participant is a woman who is a vegetarian includes calculating the probabilities of other events. Several concepts are introduced while answering this question.

Let W be a simple event that a participant is a woman and the simple or the marginal probability of W represented by P(W) is 0.40, that is 40 percent of total participants are women.

Let V/W be a simple event that a participant is a vegetarian among the women participants. The conditional probability of vegetarians among women participants symbolized by P(V/W) is 0.75, that is 75 percent of women participants are vegetarians. Here the occurrence of the event of vegetarian women participants is dependent on the event of occurrence of women participants.

Let (W intersection V) or (W and V) is a "AND" compound event that a participant is a woman and a vegetarian. Here, the multiplication rule of two dependent events is applied. The joint probability of two dependent events is the product of a marginal probability and the conditional probability. In this case, the joint probability of an woman participant who is a vegetarian indicated by P(W intersection V) or P(W and V) in which both events of women participants and vegetarian women among all women participants occur is the product of P(W) and P(V/W) and that is equal to 0.40 multiplied by 0.75, equal to 0.30. It means that 30 percent of the total participants are women who are vegetarians.

Saturday, March 17, 2018

Results Chain, An Exemplary Case – Basan Shrestha

I have prepared an imaginary article that could be used as a case for training and orientation on results chain to identify the goal, outcomes and interventions.

An international development agency was interested to undertake a public health project in one of the least developed countries. Experts from the agency reviewed the findings of Demographic Health Survey (DHS) and found that Nepal was one of the least developed countries having high child mortality rate for decades. DHS 1996 of Nepal data showed that the under-5 mortality rate was 118 deaths per 1,000 live births. Although that was reduced to 61 in a decade (DHS 2006) but the rate was still high. Under-5 mortality is defined as the probability of dying between birth and the fifth birthday. Then, the agency decided to undertake a project in Nepal, but was not clear which part of Nepal would be appropriate for the intervention. Then, the experts contacted Ministry of Health in Nepal to get the detailed dataset of child mortality rate in different parts of Nepal for past two decades. The MoH authority then directed the agency to New ERA in Nepal and ICF in the USA for the detailed dataset which had provided technical support to MoH to collect DHS data periodically. The international agency experts then reviewed the detailed dataset and found that one village in ………….foot hill had significantly higher under-5 mortality rate of 95 in 2006.  Then, the agency selected the village and undertook public health project for a decade. Afterward a decade, the same experts from the agency visited to evaluate the project achievement in 2017.

The experts started journey towards the village and noticed several changes. They noticed that open fecal discharge along the village roads were non-existent which was highly prevalent a decade ago. There were no bad smells, rather flowers were found blooming and spreading good smells along the roads. Every house in the village had toilet. Some houses had pit toilets and others had drained toilets. The experts interacted with the community members about the changes and noticed that some offenders in the communities a decade ago who did not favour to construct toilet in their houses were happy to share their positive attitude. Those offenders were turned to the change agents advocating for construction and use of toilet. The change agents formed the youth forum and provided training to youth volunteers and mobilized to orient community people through street drama. The change agents placed hoarding boards along the community roads and community displaying the message to encourage the construction and use of toilet and fined those defecating open. The fined money was used for awareness, cleaning and sweeping campaigns. The Village Development Committee (VDC) declared the VDC as the Open Defecation Free (ODF) zone.

The project had supported the community houses to construct biogas plants linking the animal sheds with the house toilets. The project had supported to purchase animals such as cows, buffaloes and goats for income generation as well as use of dungs for producing biogas. The project supported for fodder and forage for animals. That increased annual farm income from $1000 before the project to $1500 after the project. The household consumption of fuelwood for cooking purpose decreased from 800 kg of fuelwood to 300 kg per months after the project.


The project had supported to construct the toilets in the schools and public places and also the biogas plants linking the toilets. The project had supported to construct water collection ponds and electric water pumps for water supply in the schools and public places. Besides, the project had supported for household water supply system for drinking and sanitation purposes. As a result, people started to drink hygienic water and also use and clean toilet in their houses, schools and public places. The community people shared that the diarrhea and dysentery related check up and consultation visit to the health post reduced from every month to only two times a year. On the top of that, the District Public Health Office record showed that the under-5 mortality rate reduced to 35 over the decade. DHS 2016 shows that the current under-5 mortality rate for Nepal is 39.

The agency experts visited local government agencies, the Village Development Committee office, ward offices and village Water Sanitation and Hygiene Committee to interact about the project support and changes. The local government authorities shared that they did not certify any household for sale or purchase of land without verifying that the house has constructed the toilet and used it. The authorities shared that they did not certify the new building construction without the provision of a toilet and did not issue the house construction completion certificate without verifying that the house has constructed a toilet also. The authorities shared that they certified the household members for education scholarship or any other government support after verifying that the house has a toil and members are using it. The project had supported the local government agencies and committee to develop the guidelines and monitoring support for verification of toilet construction and use. Overall, several interventions were attributable to the project contributing to achieve the goal.

Friday, February 16, 2018

Database Management in Excel

Database management is important in all sectors. Database is a list of data in fields (variables) and records (cases). Columns and rows in the Microsoft Excel worksheet are used as fields and records respectively for record keeping, inventories, monitoring and evaluation to convert data into information. There are many features on data input, processing and outputs for managing database in Excel.

Input and Process

Table format in the worksheet delineates the data entry range of cells bringing the cursor to the first field of the following record after completion of the former record. Adding a new field automatically comes under an array of data. The table is named such as “data”. The name works as the source of data in the formula bar for processing and analysis.

Dropdown menu lists the response options that helps minimise data entry errors, example, district names are arranged in dropdown menu in the district field. Input and alert messages can be added to inform to select the appropriate value. Dependent dropdown menu in the next field limits the response categories in a cell based on the value in the former field. For example, once Kathmandu is selected from the dropdown list in the „district‟ field, only the Village Development Committees (VDCs) or municipalities (MPs) within Kathmandu district are listed in the “vdc” field.

Data from different sources are connected to avoid multiple entries. For example, the data template has a field to record district name and another field records the zone. A separate table of district and zone is created and linked to the “zone” field that automatically enters zone name once district is selected.

Cells can be customised to accept only the numerical values between the assigned maximum and minimum values to avoid Invalid data. Besides, there is a feature that identifies the already existing data that are invalid given the criteria.

The unique identifier cells can be customised to accept only the nonduplicating values. Besides, values from several fields can be added to create the unique identifier. For example, the first and family names of staffs in the list, district name and VDC name are combined to create a unique identifier. Duplicate values can be highlighted and removed, and the unique identifiers can be counted to identify the duplicate values.

Texts in a field can be broken down into words and placed into several fields. For example, the full name of a person in a field can be broken down into the first name, middle name if available and family name. Separating family name will help analyse staffs by caste/ ethnicity. Serial numbers are auto filled to avoid typing error. Serial numbers can be formatted to create unique identifiers. For example, if a staff dataset has a “StaffID” field.

Serial numbers can be formatted to appear “S1” as text on the first cell entered with number “1” and the same format can be auto filled in remaining cells of that field. Directly writing “S1” on a cell can also be auto filled in remaining cells, but the data value remains as S1 not “1” as in cell format customised as above.

Date of joining an organisation, for example, is used to calculate the duration of service as of certain time in decimal number of years or number of years, months and days. Job duration can be categorised as “New staff (less than 5 years)”, “Middle year staff (5 to less than ten years)” and “Old staff (ten or more years)”.

Output

Data filtration criteria is defined. Staffs aged 25 years or more can be filtered. Texts such as first names beginning with “A” can be filtered. Excel calculates values that match the defined criteria. For example, in the staff list one may be interested to know the average age of female staffs from Kathmandu district. Here, “age” is calculated taking “female” and “Kathmandu” as the criteria.

Frequency table counts the number of records by response categories. The counts can be calculated in percentage. Frequency tables can be created manually as well as using interactive features. Numeric values can be grouped to create the frequency distribution by categories.

Data summaries and presentation can be made in some other forms. Example, top three older and younger staffs by gender can be tabulated to provide information for staff recruitment strategy.

Cross tables summarise data by categorical fields, such as number of staffs by sex and ethnicity. One can choose either numeric values or percentage figures for data summary in cross tables. The numeric values may include number of counts, sum, average, maximum and minimum numbers. Column percent or row percent is again a matter of choice. Cross table is updated when the database is edited or updated with new records.

New field based on the existing fields can be created just for tabulation purpose. For example, the staff list has age of staff and salary fields. The salary age ratio field can be created for tabulation purpose to know how different are the ratios for female and male staffs. Charts are prepared to display data in graphical form using features to highlight and graphically present data bars. Colorful icons are used to visualise data and highlight top or bottom values.

Dashboard can be prepared using filter and connection features to link charts on dashboard to
visualise filtered values in different interactive charts.

Sunday, February 5, 2017

Commuting on Our Narrow, Potholed Roads: PeopleSpeak, The Himalayan Times

The government needs to promote micro-bus for short routes and narrow roads, and big buses for longer routes and wider roads. Small vehicles are not a nuisance. Small vehicles such as tuk-tuk are seen driven in busy cities like Bangkok. Micro-buses can ply within the Ring Road during office hours. Big buses should be allowed on Ring Road and outside.
Basan Shrestha, Ghattekulo Marg
5 February 2017
https://thehimalayantimes.com/opinion/commuting-narrow-potholed-roads-nepal-vehicles-road-crowd/